I Spent $340 on Monitoring Tools. Only 1 Was Worth It.
How subscription creep convinced me I needed enterprise observability for hobby projects, and the zero-cost stack that replaced it.
The Unsponsored Verdict
The Silent Subscription Creep
It started innocently enough. You deploy an API, you read an article about “distributed tracing,” and within six months your credit card statement looks like a venture-backed tech incubator:
- Tool A (Distributed APM): $79/mo
- Tool B (Log Ingestion): $45/mo
- Tool C (Synthetic Pings & Incident Escalation): $30/mo
- Tool D (Error Tracking with Session Replay): $85/mo
- Tool E (Metrics Dashboard with Fancy Heatmaps): $101/mo
Total monthly burn: $340/month.
For what? A set of four hobby applications visited by curious developers and a handful of friends.
I was paying enterprise insurance for a digital bicycle.
The Audit: What Actually Broke?
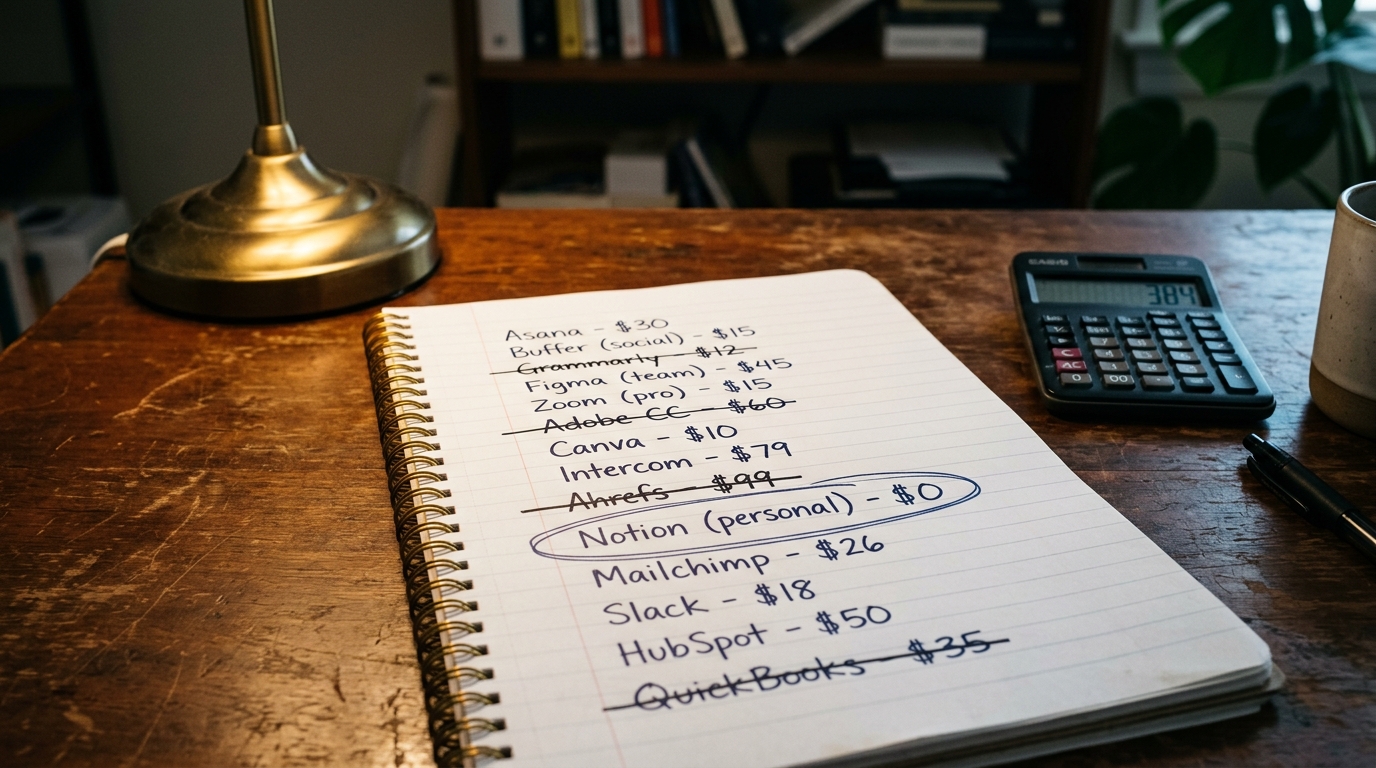
One Sunday afternoon, I sat down with a legal pad, a black marker, and a calculator. I went through the incident history of the preceding 12 months.
Across 12 months, how many production incidents had actually occurred?
- Total incidents: 4.
- How were they discovered?
- I tried logging in myself and saw a 500 error.
- A friend emailed me saying an endpoint timed out.
- A Cron job failed to update a cached JSON feed.
- An SSL certificate expired because DNS had auto-renewed incorrectly.
How many of those incidents were saved by my $340/month observability stack?
Zero.
The APM sent me 42 alerts a day about “p99 latency spikes on microservice worker #3,” which turned out to be background garbage collection. The incident dashboards were so noisy that I had routed their notifications to a silent email folder months earlier.
The One Tool That Stayed
I cancelled nine subscriptions in one afternoon. The only tool that survived the audit was a simple, free HTTP heartbeat checker:
# The reality check:
# 1. Does the URL return HTTP 200 OK?
curl -I -s https://my-service.com/health | grep "HTTP/2"

# 2. Are the error logs appended to a local file with rotation?
tail -n 50 /var/log/app.log | grep "ERROR"
If the endpoint returns 200, the site is alive. If it returns 500 or fails to respond within 5 seconds, send a ping to a free Telegram bot or a Discord webhook.
That was it.
The Replacement Stack ($0 Cost)
| Need | What I Paid $340 For | What I Use Now ($0) |
|---|---|---|
| Uptime Health | Heavyweight Synthetic Monitors ($79) | Free Cloudflare Health Checks / Uptime Kuma |
| Error Tracking | Distributed Session Replay ($85) | Plain try/catch with structured JSON logs |
| Log Storage | Cloud Log Warehouse ($45) | SQLite local event table + logrotate |
| Performance | Distributed APM Trace Graph ($131) | Browser DevTools Network tab + Lighthouse |
The lesson: You do not need enterprise observability until you have enterprise revenue. Until then, simplicity is not just cheaper—it is vastly more reliable.
Written by CA
Hobbyist developer, journalist background, Scandinavian walks. Testing AI models and web architecture on a refurbished laptop every Tuesday.